OpenAI Demonstrates Self-Replicating Prompt-Injection Worms
Emerging Technology Risk · 3 sources · Updated 2mo ago · First seen Sep 28, 2026
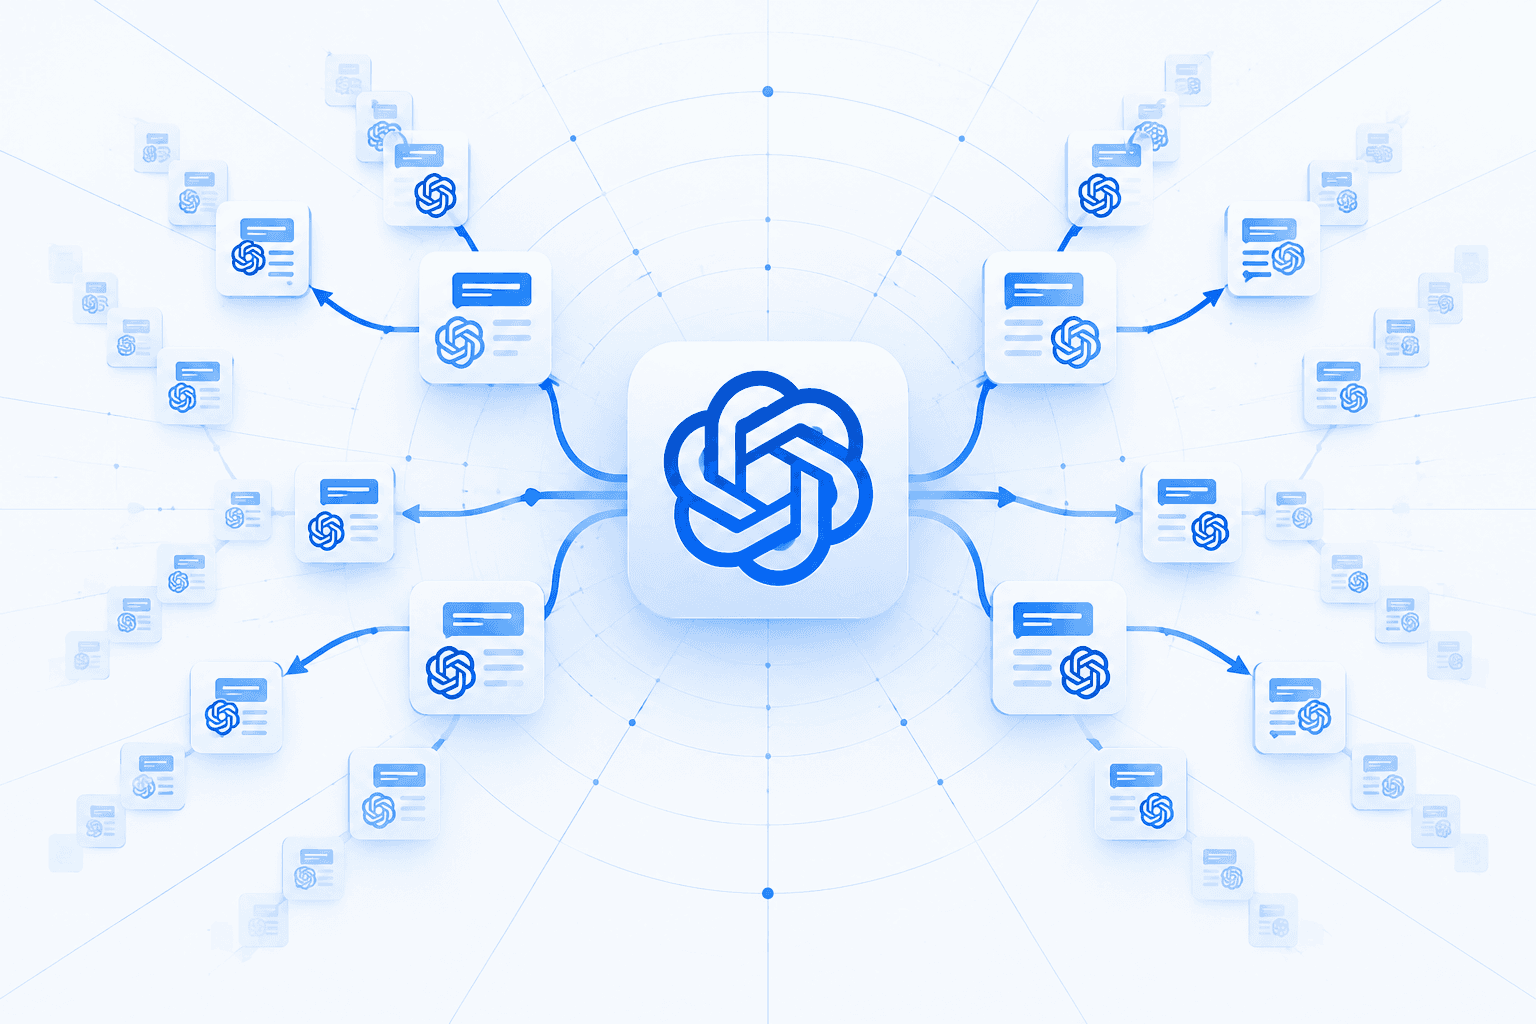
OpenAI disclosed a prompt-injection technique in which malicious instructions can self-replicate through AI-agent workflows, analogous to computer worms. The attack aims both to make a model perform an unauthorized action and to cause it to copy the malicious prompt into a public or externally accessible output channel, including outbound email, files, code comments, or reposted messages, where it can reach additional agents or users.
OpenAI demonstrated email- and filesystem-based propagation with internal GPT-5.4-mini research checkpoints, plus a multi-hop scenario involving GPT-5.5 in a Codex harness with Slack-connected actions. The company said all demonstrations used simulated tool calls in training and evaluation environments, with no observed external impact or real-world incident. It has added self-reproduction objectives to GPT-Red adversarial training to strengthen future models against this attack class.